

SWEeper-Bench: Can Agents Discover Bugs in Interactive Software?
Paper • 2610.14096 • Published • 9
The dataset viewer should be available soon. Please retry later.
Paper · Blog · Code · Benchmark
This dataset has every run behind the SWEeper-Bench paper: 5,200 runs from 42 agent configurations. For each run you get the prompt the coding agent saw, its full trajectory, the shell commands it ran against the app, its patch, and the browser verifier's trajectories and verdicts.
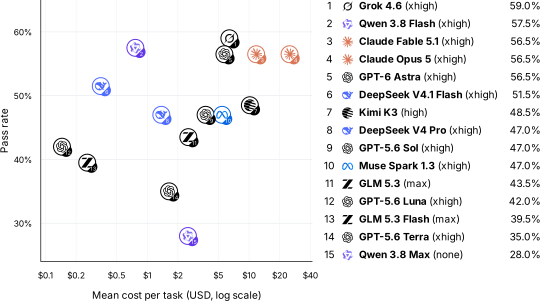
All 15 agents ran on the 200 tasks with the open-ended prompt and the browser prompt template. A task passes only when both of its behavior tests pass. A task with no prediction or evaluation counts as a fail.
| Model | Harness | Effort | Pass rate |
|---|---|---|---|
grok-4.6 |
Cursor | xhigh-fast | 59.0% |
qwen3.8-flash |
Codex | xhigh | 57.5% |
claude-fable-5-1 |
Claude Code | xhigh | 56.5% |
claude-opus-5 |
Claude Code | xhigh | 56.5% |
gpt-6-astra |
Codex | xhigh | 56.5% |
deepseek-v4.1-flash |
DeepSeek harness | xhigh | 51.5% |
kimi-k3 |
Kimi Code | high | 48.5% |
deepseek-v4-pro |
DeepSeek harness | xhigh | 47.0% |
gpt-5.6-sol |
Codex | xhigh | 47.0% |
muse-spark-1.3 |
Muse Code | xhigh | 47.0% |
glm-5.3 |
Codex | max | 43.5% |
gpt-5.6-luna |
Codex | xhigh | 42.0% |
glm-5.3-flash |
Codex | max | 39.5% |
gpt-5.6-terra |
Codex | xhigh | 35.0% |
qwen3.8-max |
Codex | none | 28.0% |
type |
What changes | Runs |
|---|---|---|
ablation-prompt |
The agent gets a description of the bug (specified prompt). Five agents pass 96.0% to 96.5%. |
1,000 |
ablation-template |
The prompt no longer asks the agent to test in a browser (non-browser template). |
400 |
ablation-harness |
gpt-5.6-luna in four other harnesses, on a 40-task subset. |
160 |
ablation-time |
Time budgets of 20, 40, 60, and 80 minutes, on the same 40 tasks. | 640 |
runs.csv has one row per run, and the dataset viewer shows it as the runs split.
| Column | Meaning |
|---|---|
run_id |
Folder name of the run |
task_id |
sweeper-001 through sweeper-200 |
model, harness, effort |
The agent |
prompt |
scoped (open-ended) or specified (bug described) |
template |
browser or non-browser |
set |
200 (all tasks) or 40 (ablation subset) |
time_budget |
unlimited or minutes |
type |
main or one of the ablations above |
target, preservation |
Verdict of each behavior test |
overall |
pass only when both tests pass |
hf_url |
Link to the run's folder |
from huggingface_hub import hf_hub_download, snapshot_download
import pandas as pd

repo = "zlab-princeton/SWEeper-Bench-traces"
runs = pd.read_csv(hf_hub_download(repo, "runs.csv", repo_type="dataset"))

run = runs.query("model == 'gpt-6-astra' and task_id == 'sweeper-001' and type == 'main'").iloc[0]
path = snapshot_download(repo, repo_type="dataset", allow_patterns=f"{run.run_id}/*")
The whole dataset is about 5 GB in 65,000 files. To get all of it, git clone https://huggingface.co/datasets/zlab-princeton/SWEeper-Bench-traces is much faster than snapshot_download.
<run_id>/
  metadata.json                 Same fields as the runs.csv row
  prediction/
    prompt.txt                  Prompt given to the coding agent
    harness.stdout.txt          Agent output, including its trajectory
    harness.stderr.txt          Agent error output
    trajectory.jsonl            Claude Code only: stream events
    final.txt                   Claude Code only: final message
    status.shell.txt            Commands the agent ran in the app container
    patch                       The agent's patch
  evaluation/
    result.json                 Verdicts for both behavior tests
    <test-id>/
      prompt.txt                Verifier instructions
      trajectory.jsonl          Verifier trajectory in the browser
      last-message.txt          Verifier's final verdict
Some files are missing when a run stopped before that stage. The hf_url inside each metadata.json points to the original upload; use the one in runs.csv.
This dataset is released under CC BY 4.0. Traces quote source code from the benchmark applications, which keep their own licenses.
@article{yao2026sweeperbench,
  title   = {SWEeper-Bench: Can Agents Discover Bugs in Interactive Software?},
  author  = {Yao, Yang and Chen, Haozhe and Kang, Bingyi and
             Narasimhan, Karthik R and Liu, Zhuang},
  journal = {arXiv preprint arXiv:2610.14096},
  year    = {2026}
}