| --- |
| library_name: transformers |
| base_model: openai/gpt-oss-20b |
| tags: |
| - text-generation |
| - search |
| - retrieval |
| - harness-1 |
| --- |
| |
| # Harness-1 |
|
|
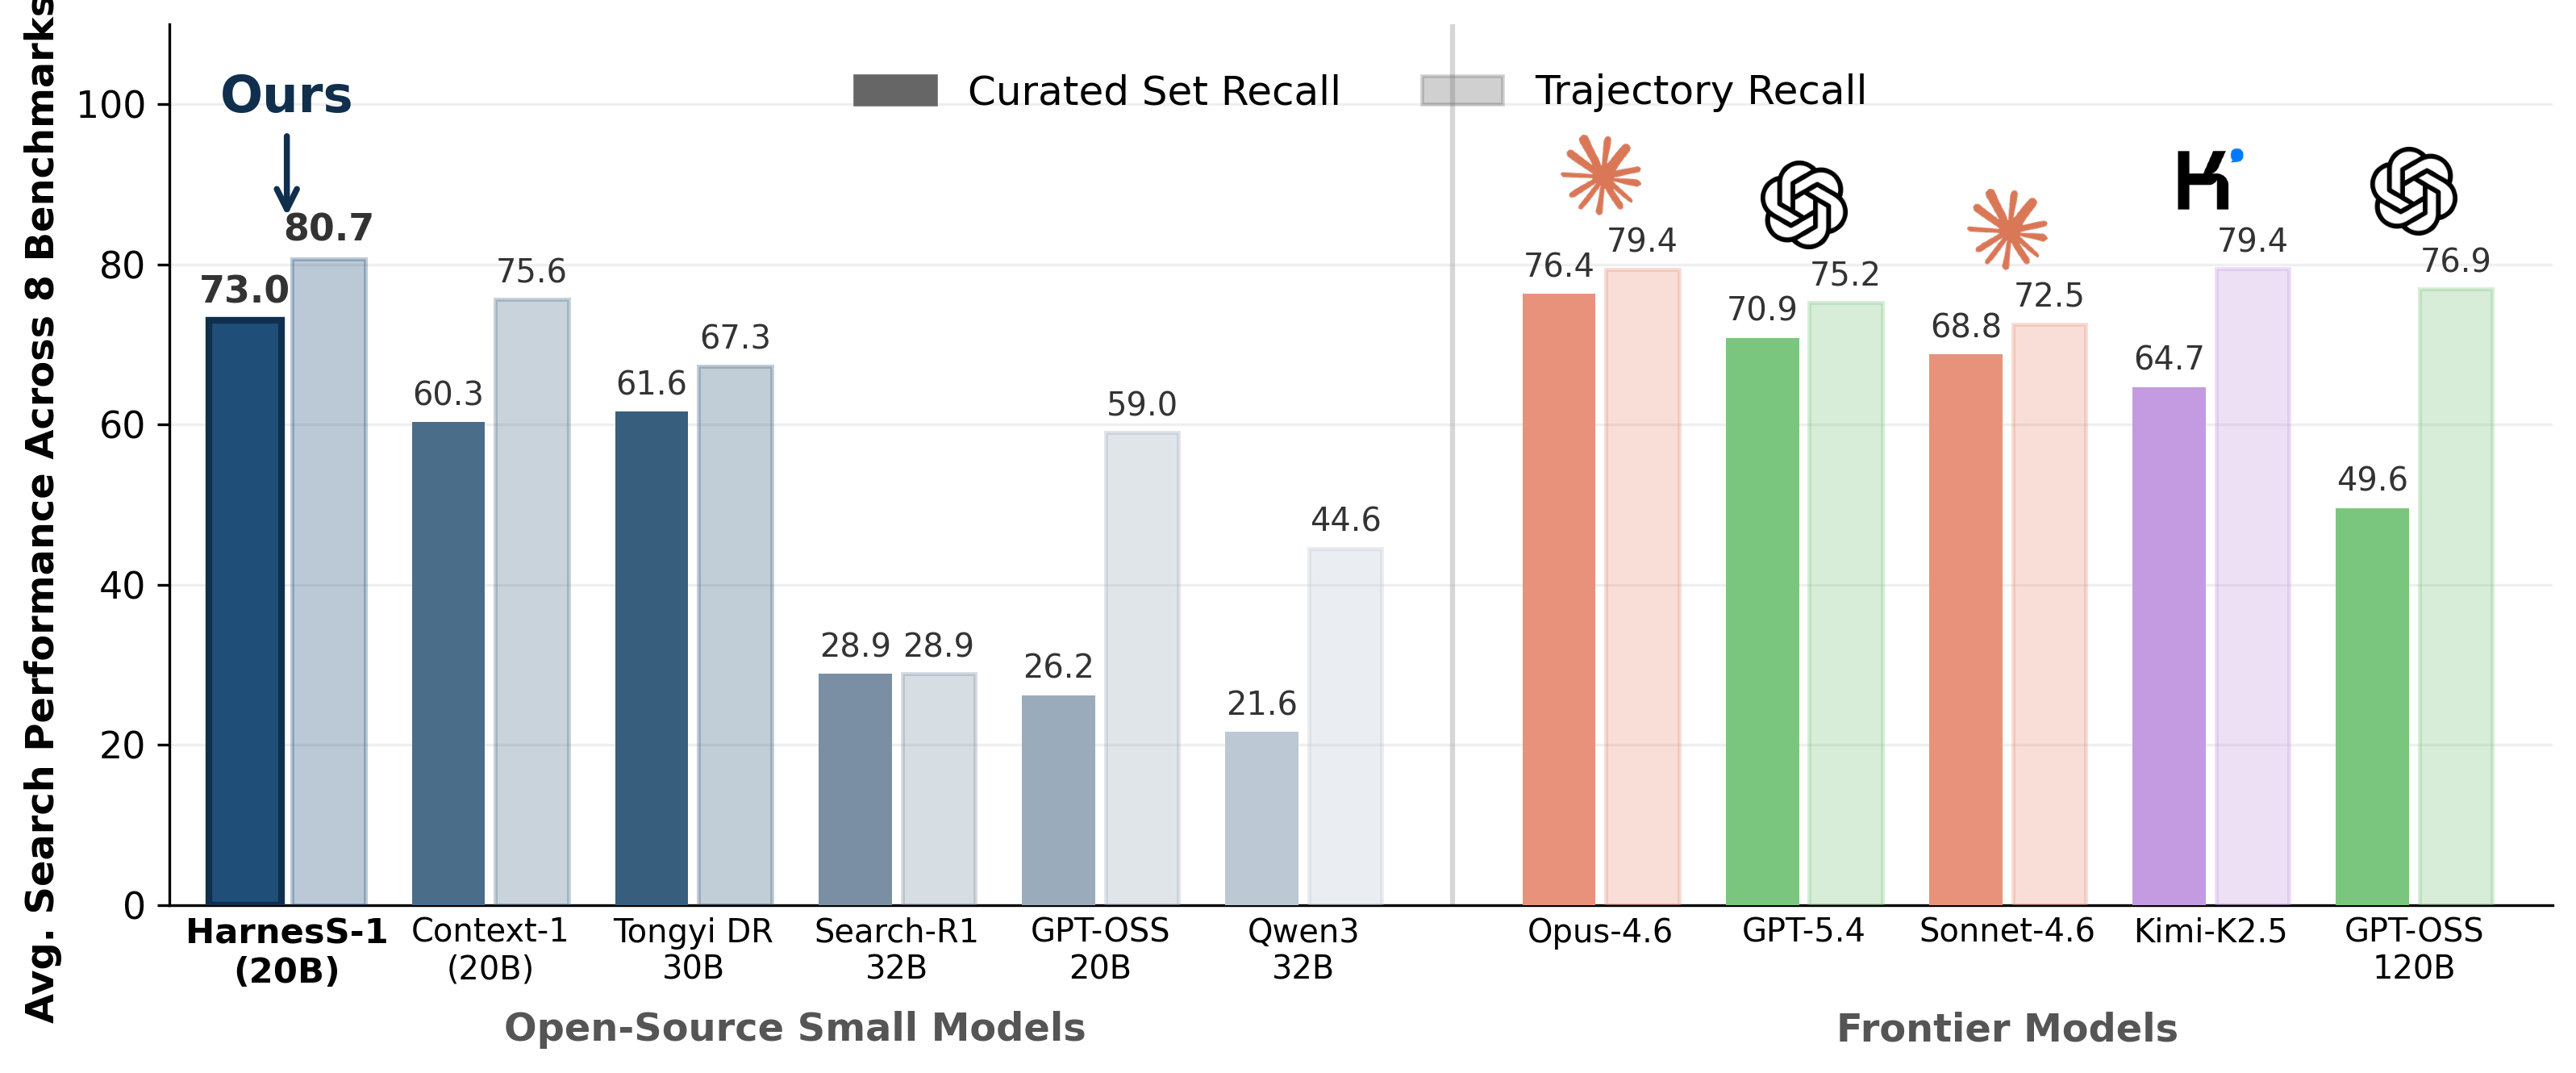
| A 20B search agent that matches frontier AI's search capability. |
|
|
| ## News |
|
|
| - **2026-06-15:** Released Harness-1 training data and retrieval corpora at [pat-jj/harness-1-train-data](https://huggingface.co/datasets/pat-jj/harness-1-train-data): 899 SFT trajectories, 3,453 RL SEC train-split examples, and corpus shards for BrowseComp+, web, patents, and SEC. |
| - **2026-06-15:** Released the full merged Harness-1 checkpoint as standard Hugging Face `safetensors` shards. |
|
|
|  |
|
|
| Code: https://github.com/pat-jj/harness-1 |
|
|
| Paper: https://arxiv.org/abs/2606.02373 |
|
|
| Training data and corpora: https://huggingface.co/datasets/pat-jj/harness-1-train-data |
|
|
| Tinker inference example: https://github.com/pat-jj/harness-1/blob/main/inference/tinker_inference.md |
| |
| vLLM inference example: https://github.com/pat-jj/harness-1/blob/main/inference/vllm_h100_browsecompplus.md |
| |
| This repository contains the full merged Harness-1 release checkpoint. The model |
| is merged into the `openai/gpt-oss-20b` base model and saved as standard Hugging |
| Face `safetensors` shards. |
| |
| ## Training Data And Corpora |
| |
| The Harness-1 training data and retrieval corpora are published separately as |
| [pat-jj/harness-1-train-data](https://huggingface.co/datasets/pat-jj/harness-1-train-data). |
| It contains one `train` split with a `stage` column: |
| |
| - `sft`: 899 raw GPT-5.4-generated v8d SFT trajectories produced by `generate_sft_ultra_0417.py`. |
| - `rl`: 3,453 SEC training-split query records used for RL (`TRAIN_DATASETS=sec`, `RL_QUERY_SPLIT=train`). |
|
|
| The same dataset repo also includes retrieval corpora under `corpora/`: |
|
|
| - `corpora/browsecompplus/test`: 1,144,886 chunks. |
| - `corpora/web/train`: 219,388 chunks. |
| - `corpora/web/test`: 54,735 chunks. |
| - `corpora/patents/train`: 104,842 chunks. |
| - `corpora/patents/test`: 35,551 chunks. |
| - `corpora/sec/train`: 2,115,106 chunks. |
|
|
| ```python |
| from datasets import load_dataset |
| |
| ds = load_dataset("pat-jj/harness-1-train-data", split="train") |
| sft = ds.filter(lambda row: row["stage"] == "sft") |
| rl = ds.filter(lambda row: row["stage"] == "rl") |
| |
| sec_corpus = load_dataset( |
| "parquet", |
| data_files="hf://datasets/pat-jj/harness-1-train-data/corpora/sec/train/*.parquet", |
| split="train", |
| ) |
| ``` |
|
|

